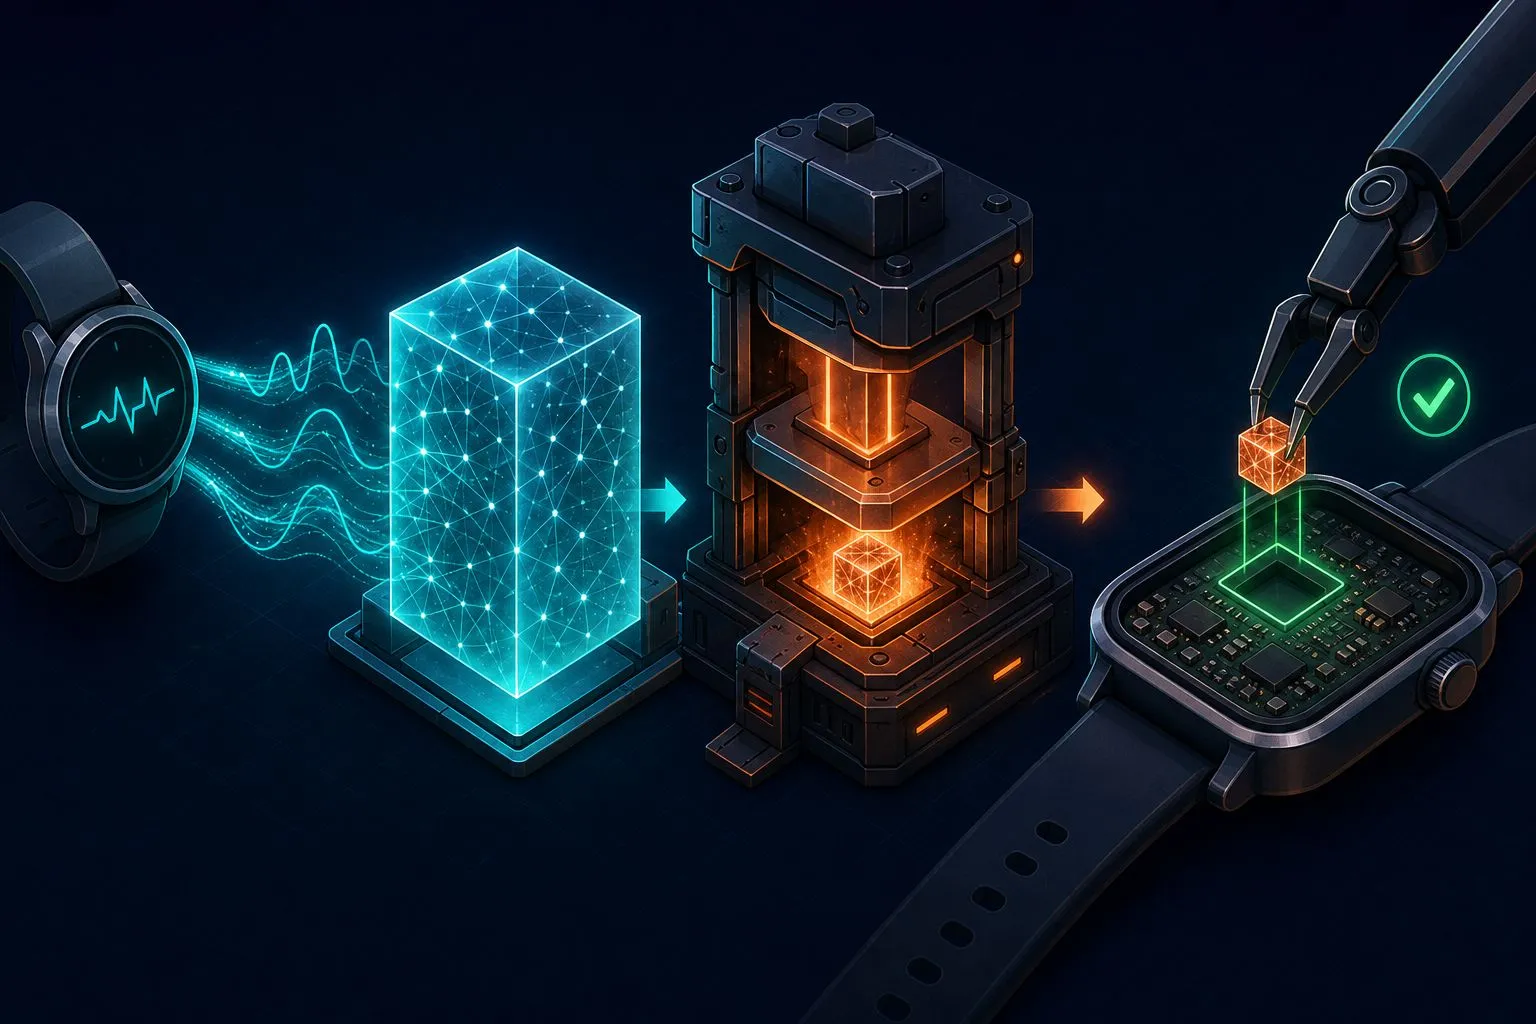
From Sensor Windows to a 100 KB Model: Deploying the HAR CNN
The last two posts took an activity recognition model from an evaluation protocol that doesn’t lie to a diagnosis of where it actually fails. A model you understand but can’t ship is a lab exercise, so this post closes the series the way real sensor projects close: turn the thing into a deployment artifact and measure what survived. It’s also a natural experiment I’ve wanted to run since July — my quantization post documented a set of traps on a 2D image CNN, and I claimed they were general. A 1D convnet on sensor data is a different architecture, different tensor shapes, different kernels. Same traps?
The subject: yesterday’s three-layer 1D CNN, 95,878 parameters, trained on the official UCI HAR split to 93.99% test accuracy. As a float32 ONNX file it weighs 374 KB — which sounds like nothing until you remember the target class for this kind of model isn’t a desktop but a wearable MCU with flash and RAM measured in hundreds of kilobytes, sharing space with a radio stack and a firmware image. Size is the budget that matters first.
Export: boring, by design
The ONNX export itself gave me nothing to write about, which is its own small victory — the export post’s checklist (dynamic batch axis, load the artifact, compare outputs) has become muscle memory. Worst-case logit difference against PyTorch: 4.3e-06 across all 2,947 test windows, accuracy identical to the fourth decimal. Conv1d, BatchNorm1d, MaxPool1d, and AdaptiveAvgPool1d all have clean, well-traveled ONNX lowerings. Ten minutes, including the parity check.
The traps fire again, in order
Then quantization, where the July post’s two landmines were waiting exactly where I’d mapped them.
First: quantize_dynamic with weight_type=QuantType.QInt8 produced a file that writes successfully and loads never — NOT_IMPLEMENTED : Could not find an implementation for ConvInteger(10). Identical failure to July, now on a Conv1d-based graph: the quantizer emits signed-int8 ConvInteger nodes and onnxruntime’s CPU provider still only implements the unsigned variant. The tool and the runtime that rejects its output still ship in the same package, one minor version later. My session-construction-immediately-after-writing habit caught it in seconds.
Second: dynamic quantization with QUInt8 — the variant that does load — ran batch-1 inference 4.2x slower than fp32 (0.262 ms vs. 0.062 ms). July’s post found dynamic quantization made a 2D CNN several times slower because computing activation scales on every inference swamps the integer-math gains for convolutions; the 1D case reproduces it almost exactly. Dynamic quantization remains a matmul-model tool that happens to accept conv models without complaint.
So: both claimed generalizations held. I’ll take the win, but honestly the better payoff was time — in July these two surprises ate most of an afternoon; today, with the failure modes already written down, the whole quantization step took twenty minutes including the reruns. Documenting your own traps has a measurable ROI, it just accrues to a future version of you.
What static int8 delivered
Static quantization with 200 calibration windows (drawn from training data, same normalization as inference — the calibration-mismatch trap from July also still applies):
| model | size | accuracy | agreement with fp32 | batch-1 latency (desktop CPU) |
|---|---|---|---|---|
| fp32 ONNX | 374 KB | 93.99% | — | 0.062 ms |
| dynamic quint8 | 100 KB | 93.93% | 99.69% | 0.262 ms |
| static int8 | 103 KB | 93.86% | 99.69% | 0.033 ms |
Size: 3.6x smaller, both methods — the one promise quantization always keeps, now confirmed on a second architecture. Accuracy: static int8 lost 0.13 points, which on this test set is four windows out of 2,947; the model disagrees with its fp32 parent on nine windows total. Given yesterday’s finding that the dominant error mode is a physical sit/stand ambiguity worth hundreds of windows, the quantization penalty is a rounding error on the problems this model actually has.
The latency column is a decoy
Static int8 also ran 1.9x faster than fp32, and I want to talk myself out of celebrating that, because for this workload the latency column is close to meaningless. HAR windows are 2.56 seconds with 50% overlap — the model runs once every 1.28 seconds. At 0.033 ms per inference, the classifier occupies 0.003% of its real-time budget; at fp32’s 0.062 ms it occupied 0.005%. Both are so far inside the budget that speed was never the constraint. This echoes the ResNet18 finding from July — quantization’s speedup on a desktop CPU is frequently a non-event — but with a sharper conclusion for sensor work: the wins that matter here are the 3.6x flash footprint, the proportional drop in memory traffic (which on battery-powered hardware is energy), and the fact that many MCU-class targets execute int8 natively but do float either slowly or not at all. For a wearable, int8 is often the admission ticket, not the optimization.
The honest caveat attached to all of this: my measurements ran on a desktop x86 CPU, because that’s what’s on my desk. The ratios I’d trust to transfer are size and accuracy; the latency numbers are illustrations, and on a Cortex-M the absolute picture shifts by orders of magnitude in ways only a measurement on the actual silicon can settle. The July post said the same thing and it remains the least skippable sentence in either post.
Series ledger
Three posts, one model: split by subject or the number lies; read the confusion matrix or the number hides the mechanism; quantize with the traps mapped and the artifact costs four windows of accuracy for a 3.6x smaller flash footprint. The 374 KB float model and the 103 KB int8 model tell the same sit/stand lies to the same difficult subjects — nothing about deployment fixed the model’s actual problem, which is a thing deployment never does. That fix is still waiting in the calibration idea from yesterday’s post, and it’s a firmware feature, not a quantization flag.