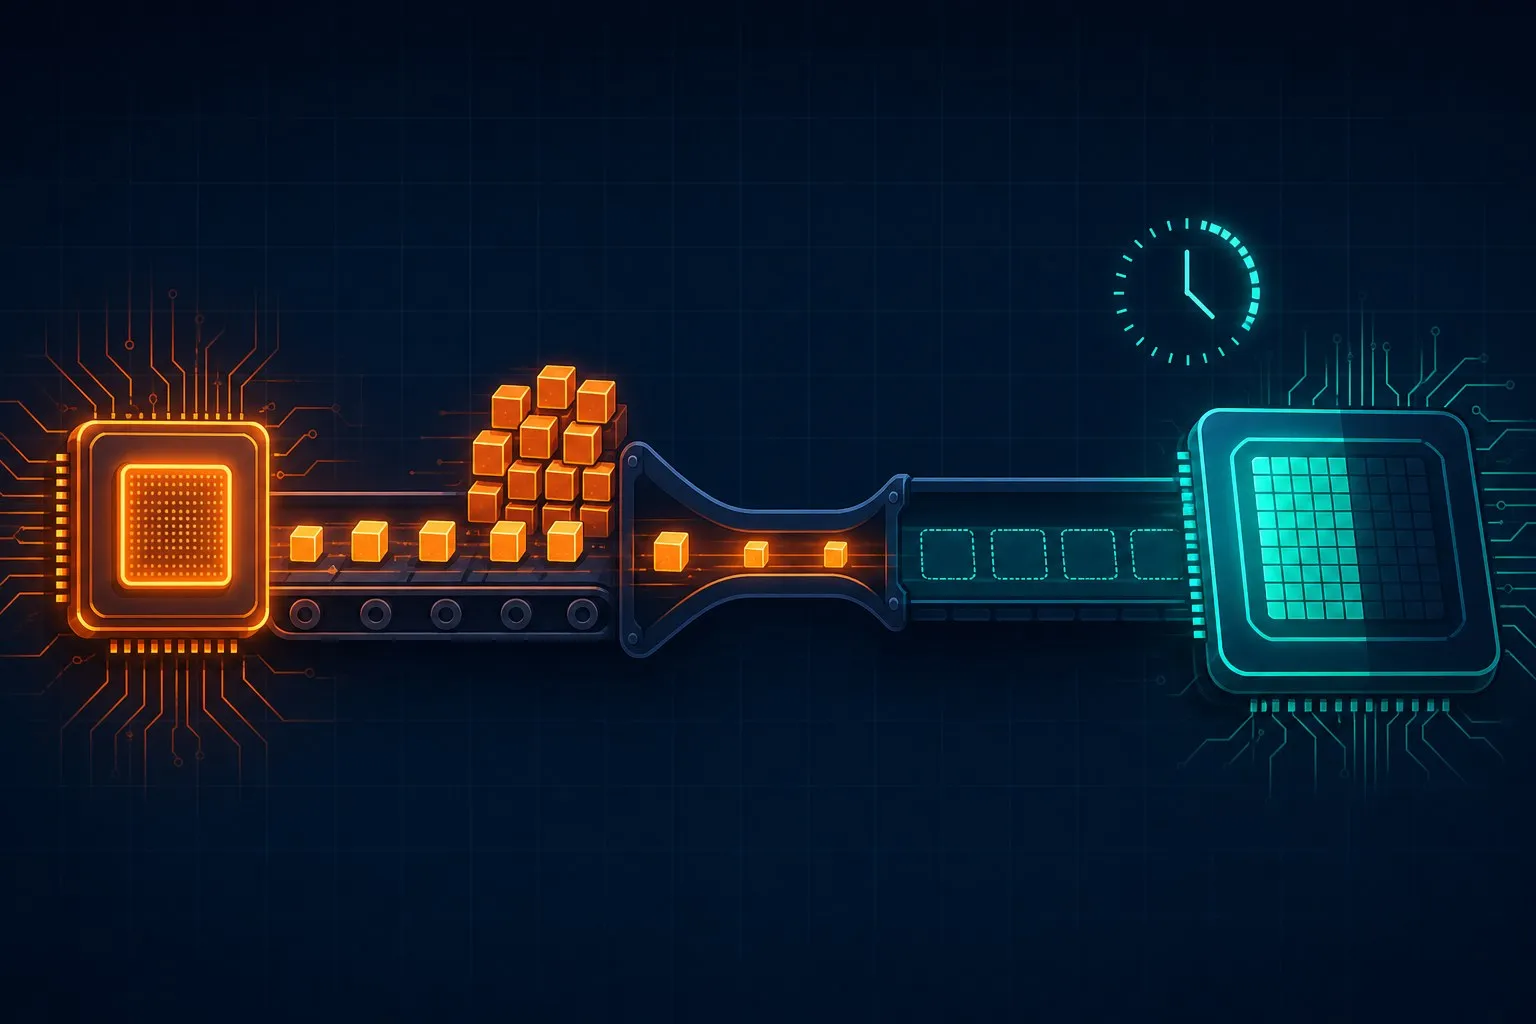
Is Your GPU Actually Busy? Diagnosing CPU-GPU Bottlenecks in PyTorch
In image processing work, the preprocessing step is rarely trivial — decoding, resizing, normalization, and augmentation can easily cost more CPU time than the model costs GPU time. The first time I profiled one of my own training runs, the uncomfortable discovery was that the GPU I was worried about “not being fast enough” was spending a large share of each epoch simply waiting for the CPU to hand it the next batch.
Optimizing deep learning pipelines is often less about tweaking model architecture and more about understanding the silent friction between your code and the underlying hardware. When training or inference slows down, the culprit is usually hidden in the interplay between CPU-bound data preprocessing and the GPU’s asynchronous execution. Before you start refactoring your model layers, you need to profile to see where your pipeline is actually stalling.
Understanding the Pipeline: CPU vs. GPU
A typical PyTorch training loop follows a producer-consumer pattern. Your CPU is responsible for loading data, applying augmentations, and moving tensors to the device, while the GPU executes the forward and backward passes. If your CPU cannot feed the GPU fast enough, the GPU sits idle—a state known as being “data-starved.” Conversely, if your model is overly complex for your hardware, the GPU becomes the bottleneck.
To identify which side of this equation is lagging, you must look beyond total execution time and examine the timeline of operations. Profiling allows you to visualize these overlapping tasks and determine if the GPU is waiting for the next batch to be prepared.
Leveraging the PyTorch Profiler
PyTorch provides a built-in profiler that hooks directly into the Autograd engine. Instead of manually timing code blocks with Python’s time module, which often introduces overhead and lacks insight into GPU events, you should use the torch.profiler context manager.
When setting up your profiler, you should:
- Enable Record Shapes: This allows you to see the memory footprint of individual operations.
- Enable GPU Profiling: If you are running on CUDA, ensure the profiler is capturing kernel execution times to differentiate between CPU-side overhead and actual GPU kernel duration.
- Trace Export: Export the profile as a Chrome Trace format file. This allows you to open the results in
chrome://tracingor the Perfetto UI, where you can zoom into individual iterations to see if Autograd tasks (likebackward) are consuming excessive CPU cycles.
A minimal setup that covers all three points:
import torch
from torch.profiler import profile, schedule, ProfilerActivity

with profile(
    activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA],
    schedule=schedule(wait=1, warmup=1, active=3),
    record_shapes=True,
    on_trace_ready=torch.profiler.tensorboard_trace_handler("./log"),
) as prof:
    for step, (data, target) in enumerate(loader):
        train_step(model, data, target)
        prof.step()
        if step >= 5:
            break
The schedule matters more than it looks: profiling every step distorts the timings you are trying to measure, so skipping the first iterations (which include CUDA context setup and worker spin-up) and sampling a few steady-state steps gives a far more honest picture. The telltale signature of data starvation in the resulting trace is a repeating pattern of GPU idle gaps at the start of every iteration, right before the forward pass kernels launch.
One Windows-specific gotcha I ran into while testing this exact snippet: the run completed without any exception, but no trace file ever appeared — only an easy-to-miss Failed to open ... .pt.trace.json line buried in the log. The cause turned out to be non-ASCII characters in my machine’s hostname, which the profiler embeds in the trace filename by default and then fails to write. The fix is one argument: tensorboard_trace_handler("./log", worker_name="worker0"). If your traces silently go missing on Windows, check that before you suspect your code.
Addressing Data Loading Bottlenecks
If your profile indicates that the DataLoader is the primary source of delay, the solution is usually found in the num_workers and pin_memory configurations.
When num_workers is set to 0, data loading happens in the main process, blocking your model execution. Increasing this value enables multi-process data loading. However, simply setting this to a high number can lead to context-switching overhead. A useful rule of thumb, based on documentation, is to start with the number of CPU cores and tune downward to find the sweet spot for your specific data augmentation pipeline.
Common strategies for improving data loading throughput include:
- Pin Memory: Setting
pin_memory=Truein yourDataLoaderallows for faster data transfer from CPU to GPU by using page-locked memory, which is essential for maximizing PCIe bandwidth. - Pre-fetching: Ensure your data is stored in a format that allows for fast random access, such as memory-mapped files or sharded binary formats, rather than thousands of small individual files.
- Transform Placement: Perform heavy image augmentations or tensor conversions on the GPU if possible, rather than using CPU-based libraries that create significant serial bottlenecks.
Analyzing Autograd and Memory
Sometimes the bottleneck isn’t data; it’s the way Autograd tracks operations. Every tensor operation creates a node in the Autograd graph. If you are performing operations that aren’t strictly necessary for the gradient calculation, you are wasting cycles.
Use torch.autograd.profiler to identify operations that contribute significantly to the total memory footprint. If you see high overhead in backward passes, check for unnecessary tensor cloning or large intermediate values being stored. Utilizing torch.utils.checkpoint can reduce memory usage at the cost of additional computation, which might be a necessary trade-off if your bottleneck is memory-induced page swapping.
Conclusion
Profiling is not a one-time task but an essential part of the iterative development process. By using the PyTorch Profiler to distinguish between CPU-bound data loading and GPU-bound compute tasks, you shift from guessing to engineering. Start by visualizing the timeline of your operations, optimize your DataLoader settings, and ensure your memory management is efficient before scaling your models further. Clear visibility into your pipeline ensures that your compute resources are always fully utilized.