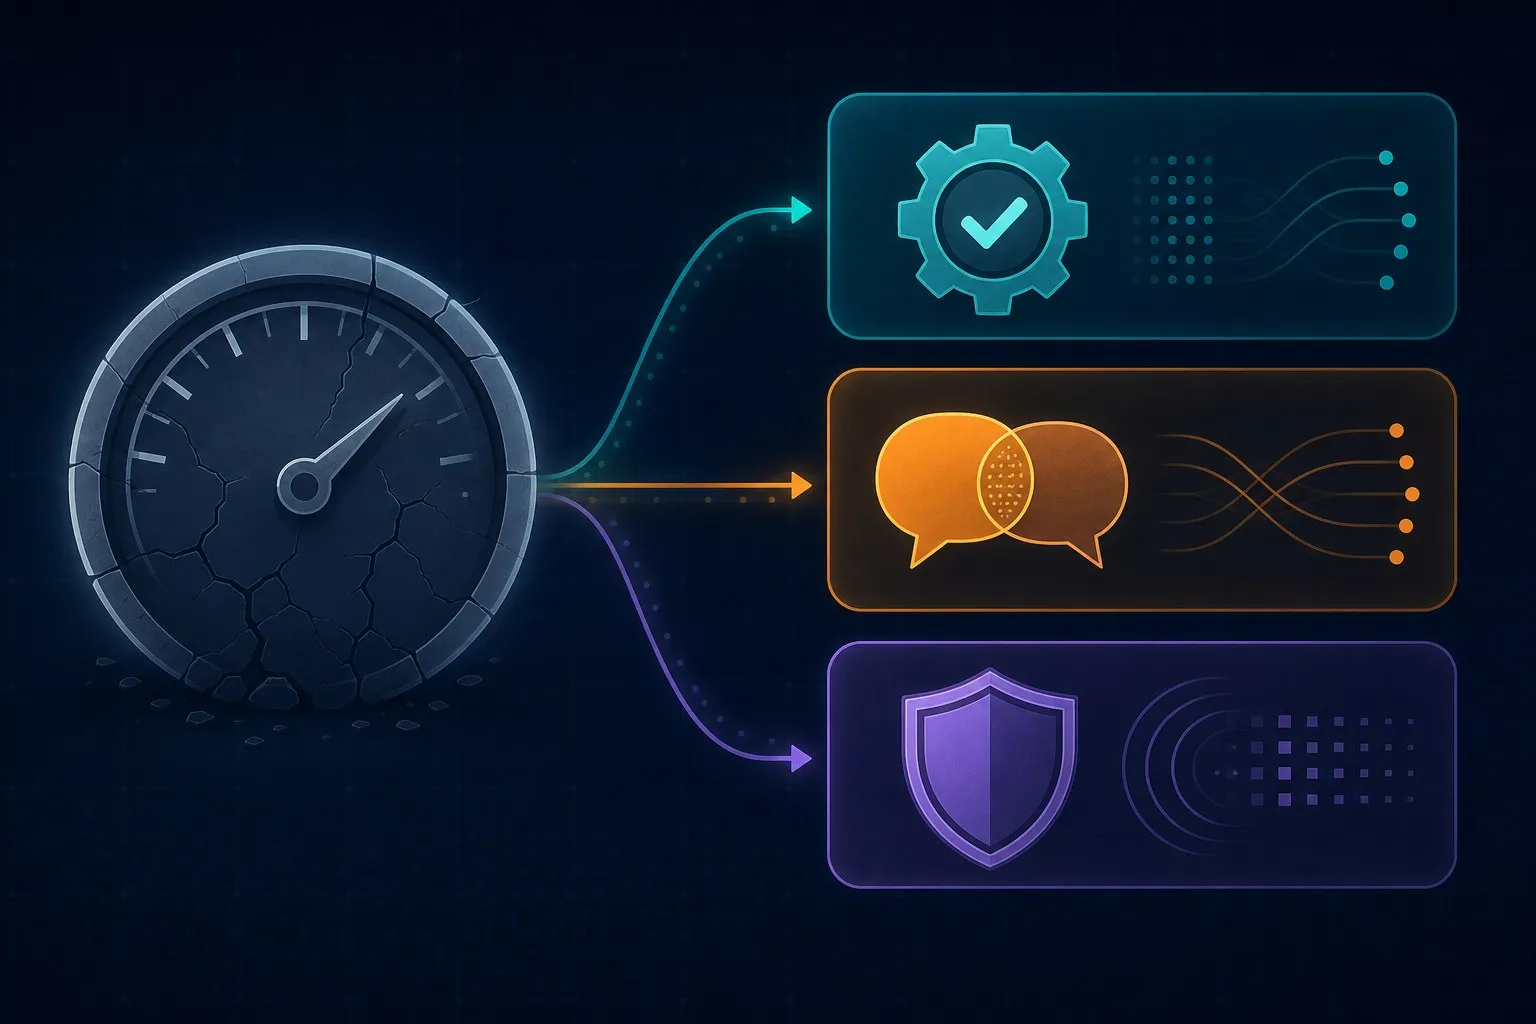
Why Perplexity is a Vanity Metric for Modern LLM Evaluation
My background is in signal processing, where we would never ship an algorithm based on a single aggregate statistic — you look at error distributions, edge cases, and failure modes on real data. So when I started integrating LLMs into my own tooling and saw model comparisons based almost entirely on perplexity, it struck me as judging a camera by its megapixel count: correlated with quality, but nowhere near sufficient.
Let me be fair to perplexity first, because “vanity metric” is a strong charge. Perplexity measures how confidently a model predicts the next token on a held-out corpus, and for its intended job — tracking pre-training progress, comparing checkpoints trained on the same data — it is genuinely useful. The problem starts when it escapes that context and becomes a proxy for “this model is better at your task.” It measures prediction in a vacuum. Your task does not happen in a vacuum.
The lesson I keep relearning: proxy metrics lie in both directions
I got a vivid demonstration of this recently in a completely different domain. While quantizing a model to int8, I compared raw outputs between the original and quantized versions and found a worst-case deviation of 2.34 — a number that looked catastrophic next to the float-precision diffs I was used to. Then I measured what mattered: the two models agreed on 99.5% of actual predictions, and test accuracy was unchanged. The proxy metric screamed; the task metric shrugged.
Perplexity fails the same way, in both directions. A model can post excellent perplexity on general text and still mangle your JSON schema, hallucinate a field name, or ignore the one constraint your pipeline depends on — the proxy shrugs while the task screams. And a model fine-tuned toward terse, structured outputs can show worse perplexity on free-form text while being strictly better at the job you hired it for. If a single scalar can move in the wrong direction for both false positives and false negatives, it cannot be your acceptance criterion.
What I check instead: three layers
When an LLM sits inside a pipeline, I treat it like any other component — a thing that accepts inputs and must emit outputs the next stage can consume. That framing gives you three layers of evaluation, in order of how cheap they are to automate:
1. Functional correctness. Does the output run, parse, or validate? For anything executable or structured, this is binary and fully automatable: parse the JSON against the schema, execute the generated query against a staging database, run the generated code against a test suite. This is the layer public code benchmarks like HumanEval operationalize — pass/fail on execution, not resemblance to a reference answer. In my own tooling this layer catches the large majority of failures, and it costs almost nothing to run.
2. Semantic alignment. For open-ended text where exact match is meaningless, embedding-based similarity against a reference (cosine similarity on sentence embeddings, BERTScore) gives a tolerant but quantifiable check — synonyms and rephrasings pass, actual meaning drift fails. The threshold is empirical and task-specific; treat it like any other tuned parameter, with a validation set, not a number copied from a blog post. Including this one.
3. Guardrail compliance. Format constraints, policy constraints, “never do X” rules. These deserve their own layer because they fail independently of quality — a response can be correct, fluent, and violate the one formatting rule your parser depends on. Cheap regex-level checks here have saved me from silent pipeline corruption more than once.
For subjective qualities that none of these layers capture — tone, style adherence, judgment calls — the LLM-as-a-judge pattern (a stronger model grading a weaker one against a rubric) is the practical compromise the field has settled on. It works, with a caveat I’d underline: log the judge’s ratings over time and spot-check a sample by hand. A judge model is itself an unvalidated component until you’ve done that.
The uncomfortable part: most failures are boring
Here is what actually changed my mind about evaluation, and it isn’t sophisticated: when I started logging failures from my own LLM-backed tooling, almost none of them were “the model wasn’t smart enough.” They were a truncated response that broke the parser, a field renamed from summary to Summary, a list where a string was expected, an instruction silently dropped once the context got long. Perplexity is blind to every single one of these. A schema validator catches them all, for free, on every call.
That’s the signal-processing instinct translated to LLMs: aggregate statistics are for dashboards; error distributions and failure modes are for decisions. Perplexity earned its place in pre-training curves and it can keep it. But if a number is going to gate what ships, it should be a number computed on your task, with your constraints, over your real inputs — layered from “does it parse” up through “does it mean the right thing.” Measure outcomes, not token probabilities.