num_workers on Windows: I Benchmarked the Advice I Gave You Last Week
In my post on CPU-GPU bottlenecks I passed along the standard advice for DataLoader tuning: increase num_workers, start near your core count, tune downward. It’s what the docs suggest and what every tutorial repeats. It’s also advice I had never actually benchmarked on the OS I develop on every day.
So I benchmarked it. Windows, 16-core CPU, PyTorch 2.6.0, FashionMNIST with two transform pipelines — one trivial (ToTensor + Normalize) and one deliberately expensive (random rotation, elastic deformation, Gaussian blur, roughly what a real augmentation stack costs). Batches of 256, two full epochs per configuration, tensors moved to GPU as they arrive. The measurement loop is nothing clever:
dl = DataLoader(ds, batch_size=256, shuffle=True, num_workers=nw,
                persistent_workers=persistent, pin_memory=pin)
for ep in range(2):
    t = time.perf_counter()
    for x, y in dl:
        x = x.to("cuda", non_blocking=True)
    torch.cuda.synchronize()
    print(f"epoch {ep}: {time.perf_counter() - t:.2f}s")
I timed each epoch separately, and also the wait for the first batch. That second number turned out to be where Windows hides the story.
Light pipeline: every worker count lost to zero workers
Trivial transforms, 60,000 samples, 235 batches per epoch:
| num_workers | first batch | epoch 1 | epoch 2 |
|---|---|---|---|
| 0 | 0.04 s | 6.3 s | 5.8 s |
| 2 | 2.8 s | 7.6 s | 7.7 s |
| 4 | 3.4 s | 6.1 s | 5.9 s |
| 8 | 4.5 s | 6.2 s | 6.3 s |
Read that again: two workers were consistently slower than none, and four or eight workers merely tied the single-process baseline. The tutorial advice, applied to a light pipeline on Windows, buys you somewhere between nothing and a regression.
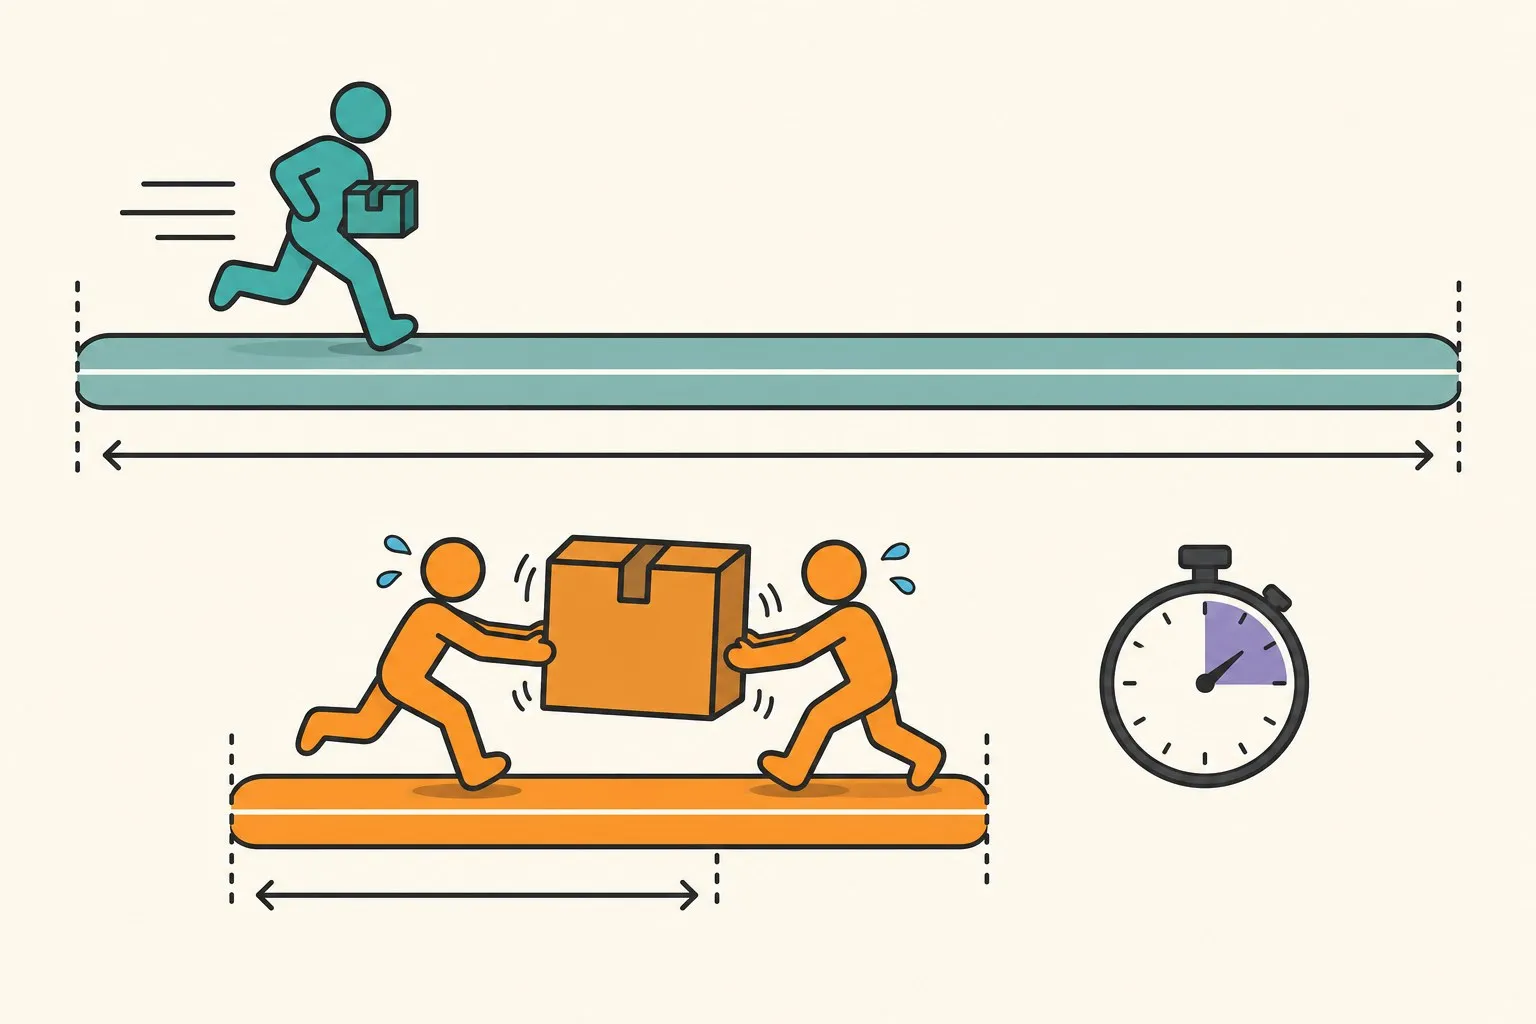
Two mechanisms are stacked against you here. The first is visible in the “first batch” column: on Windows, worker processes are created with spawn, not fork. There is no cheap copy-on-write clone of your process like on Linux — each worker starts a fresh Python interpreter, re-imports your modules, and receives a pickled copy of the dataset object. My workers took around 3 to 4.5 seconds just to come up. And because a DataLoader tears its workers down when an iterator is exhausted, that cost is paid again every single epoch by default.
The second mechanism is subtler: when a worker prepares a batch, the tensors travel back to the main process through inter-process communication. For a transform this cheap, serializing batches across process boundaries costs about as much as just doing the work in-process. Parallelism has overhead, and a ToTensor on a 28×28 image is too small a job to amortize it.
The flag that actually mattered
persistent_workers=True keeps the worker pool alive across epochs instead of respawning it. Same light pipeline, four workers:
| Configuration | epoch 1 | epoch 2 |
|---|---|---|
| nw=4 | 6.1 s | 5.9 s |
| nw=4, persistent_workers=True | 5.3 s | 2.2 s |
Epoch 1 still pays the spawn tax. But from epoch 2 onward the workers are already alive and prefetching, and the epoch time drops to 2.2 seconds — 2.7x faster than the zero-worker baseline that plain num_workers=4 couldn’t beat at all. Over a 50-epoch training run, the difference between these two rows is minutes, and it comes from a flag most examples never set because on Linux, where forking is cheap, it matters far less.
This reframed the whole exercise for me: on Windows the question isn’t “how many workers,” it’s “do the workers survive between epochs.” Worker count without persistence is rearranging deck chairs.
Heavy pipeline: workers help, but count your winnings
With the expensive augmentation stack (12,800 samples to keep runtimes sane), parallelism finally has real work to chew on:
| num_workers | epoch 1 | epoch 2 |
|---|---|---|
| 0 | 17.4 s | 17.5 s |
| 2 | 17.3 s | 17.3 s |
| 4 | 11.0 s | 10.9 s |
| 8 | 9.1 s | 9.1 s |
| 8, persistent_workers=True | 8.4 s | 4.1 s |
Workers help here — but look at the shape of it. Two workers still couldn’t beat the main process (their combined throughput roughly matched one in-process loop, minus IPC overhead). Eight workers on a 16-core machine delivered 1.9x, nowhere near eight. And once again the biggest single jump came from persistence: 17.5 seconds down to 4.1, a 4.3x improvement, with more than half of that attributable to the flag rather than the worker count.
If I had followed my own earlier advice — “start with the number of cores and tune downward” — I would have burned sixteen processes’ worth of RAM (remember, each one holds a pickled copy of the dataset) chasing a curve that flattens hard after eight.
pin_memory: measured, and measured nothing
I also ran the light pipeline with pin_memory=True, since the two flags are usually recommended in the same breath: 6.5 s vs. 6.3 s at zero workers, 2.3 s vs. 2.2 s with four persistent workers. No measurable difference — if anything, noise in the wrong direction. Pinned memory accelerates the CPU-to-GPU copy itself, and my batches (256×1×28×28, under a megabyte) are far too small for PCIe transfer to be the bottleneck. It should earn its keep with large batches of full-resolution images, but that’s a claim I’d now want to verify on the actual workload rather than repeat — this table is what repeating unverified defaults looks like.
What I actually configure now
For Windows machines, my defaults changed after this afternoon of measuring. If the transform stack is trivial — pre-tensorized data like the windowed IMU datasets I wrote about, where __getitem__ is a slice — I start at num_workers=0 and often stay there. If transforms are genuinely expensive, I use 4–8 workers, never core count. And in every configuration with workers, persistent_workers=True, non-negotiable — it was worth more than any worker-count decision in every test I ran. Short experiment scripts that iterate only an epoch or two deserve special suspicion: they pay the spawn tax on every run and never reach the steady state where workers pay off.
None of these numbers transfer directly to your machine — that’s rather the point. The benchmark script is thirty lines and runs in a few minutes, which is cheaper than one training run that spends a third of its wall-clock time respawning worker processes without you knowing. I repeated the standard advice for years before spending the afternoon that showed me where it breaks. Measure yours.