My GPU Stopped Throwing OOM Errors. What It Does Instead Is Worse
After a week of making a training step faster, this post is about the other budget: memory. The question was supposed to be simple — on my 16 GB RTX 4080 Super, how large a ResNet50 batch fits, and what do gradient checkpointing and gradient accumulation cost when it doesn’t? I expected the experiment to end the way these always end, with CUDA out of memory and a stack trace.
The stack trace never came. Something quieter and considerably worse happened instead, and it changed what the post is about.
The cliff where the error should be
Baseline configuration from the previous posts (bf16 autocast, channels_last, batch measured over 8–25 timed steps), scaling the batch up:
| batch | step time | peak memory | throughput |
|---|---|---|---|
| 256 | 234 ms | 10.9 GB | 1094 img/s |
| 320 | 301 ms | 13.5 GB | 1065 img/s |
| 384 | 2453 ms | 16.2 GB | 157 img/s |
| 448 | 18613 ms | 18.9 GB | 24 img/s |
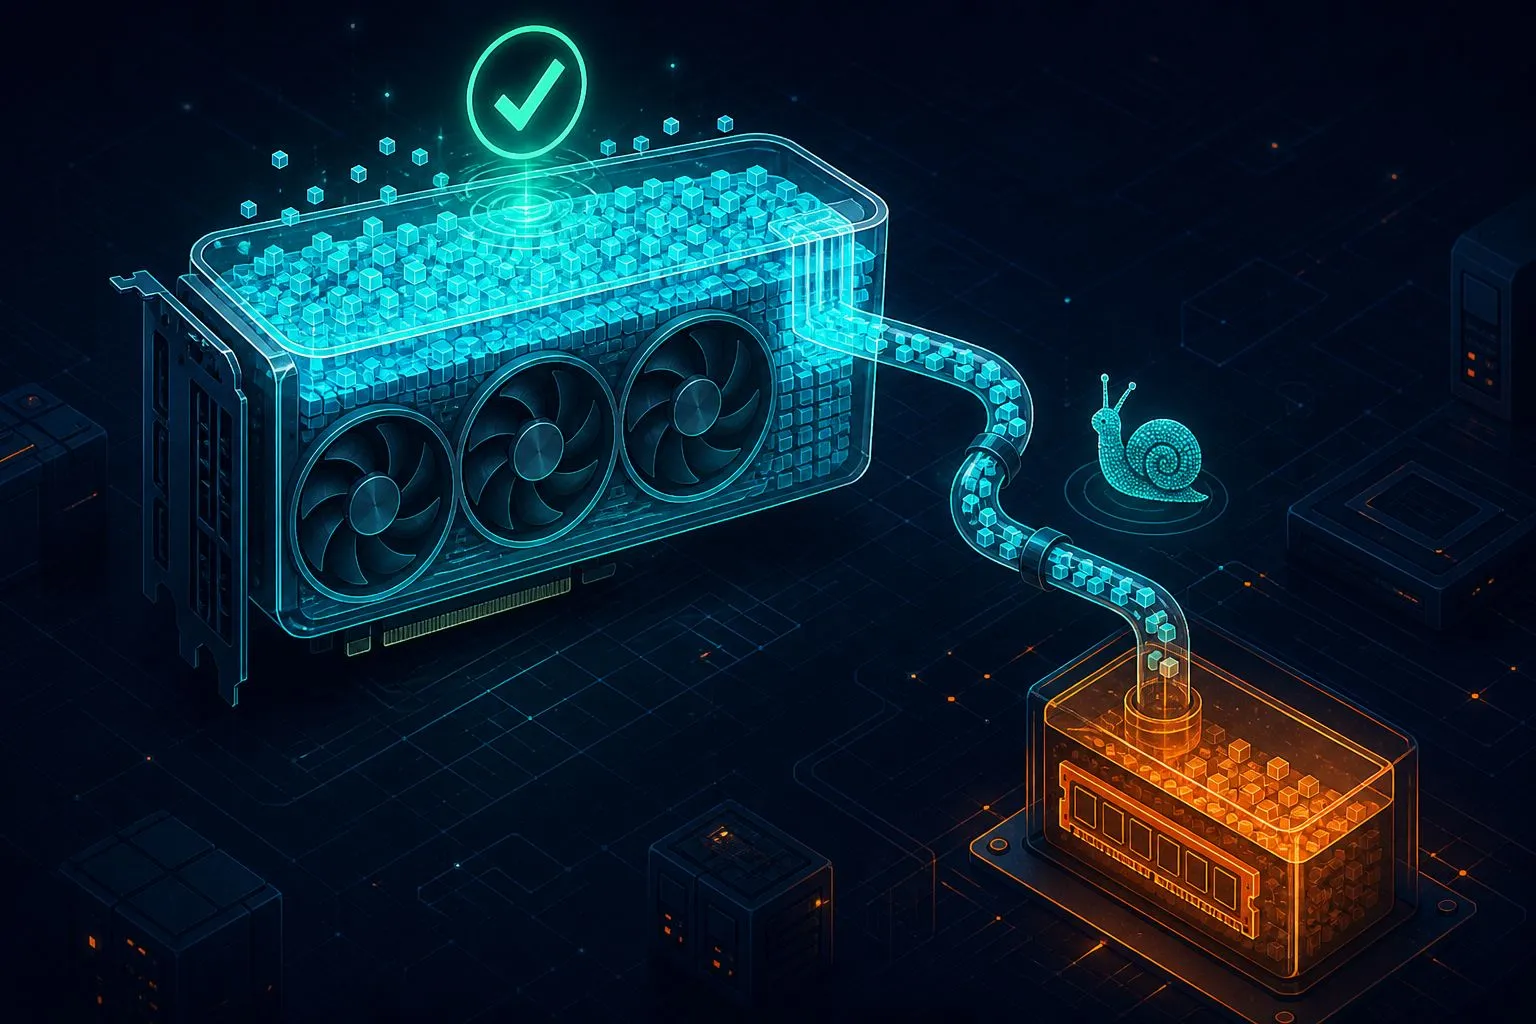
Read the memory column again: 18.9 GB peak, on a card with 16 GB. No error, no warning — PyTorch reports the allocation as if nothing happened, because from its point of view nothing did. Recent GeForce drivers on Windows ship with a sysmem fallback policy: when VRAM runs out, the driver quietly spills GPU allocations into system RAM across the PCIe bus. The training loop keeps running, every step shuttling activation memory over a link with a fraction of VRAM’s bandwidth. At batch 384 that costs 7x the throughput; at 448, 45x. A run that should have died at launch instead trains at 24 images per second — slow enough to waste a weekend, alive enough to never page you.
The failure you can’t have is the failure you can’t detect from the exception handler, so two habits changed for me on the spot. First, log torch.cuda.max_memory_allocated() next to throughput at the start of every run; a peak within spitting distance of physical VRAM plus a throughput collapse is this bug’s exact signature. Second, on Windows you can make the driver honest again — NVIDIA Control Panel → Manage 3D Settings → CUDA - Sysmem Fallback Policy → “Prefer No Sysmem Fallback” — and get your loud, immediate, debuggable OOM back. A crash at step 0 is a feature.
Lever one: gradient checkpointing
Checkpointing trades compute for memory: activations are discarded during the forward pass and recomputed during backward. In PyTorch it’s a few lines — wrap the memory-heavy trunk with checkpoint_sequential:
from torch.utils.checkpoint import checkpoint_sequential

body = nn.Sequential(model.layer1, model.layer2, model.layer3, model.layer4)

def forward_ckpt(x):
    x = model.maxpool(model.relu(model.bn1(model.conv1(x))))
    x = checkpoint_sequential(body, 4, x, use_reentrant=False)
    return model.fc(torch.flatten(model.avgpool(x), 1))
Measured at fixed batch sizes:
| batch | baseline | checkpointed | memory saved | throughput cost |
|---|---|---|---|---|
| 32 | 24.9 ms / 1.50 GB | 36.4 ms / 0.97 GB | −35% | −32% |
| 64 | 52.4 ms / 2.84 GB | 68.3 ms / 1.71 GB | −40% | −23% |
| 128 | 112.6 ms / 5.51 GB | 146.1 ms / 3.23 GB | −41% | −23% |
So the going rate on this model is roughly 40% less memory for 23–32% less throughput — recomputing the forward pass isn’t free, and nothing here suggests otherwise. Where it pays off is the ceiling: the largest batch that stayed on the fast side of the sysmem cliff went from 320 to 512 (12.3 GB peak, 792 img/s). Two footnotes the docs bury: pass use_reentrant=False, the modern implementation with fewer sharp edges; and mind batch norm — the recomputed forward means BN layers see each batch’s statistics twice per step, a subtle behavioral change that mostly washes out but is worth knowing exists when a checkpointed run doesn’t quite reproduce a baseline.
Lever two: accumulation, which won on both axes
Gradient accumulation splits a large effective batch into micro-batches, summing gradients across several backwards before one optimizer step:
opt.zero_grad(set_to_none=True)
for micro_x, micro_y in micro_batches:      # e.g. 4 chunks of 64
    with torch.autocast("cuda", dtype=torch.bfloat16):
        loss = F.cross_entropy(model(micro_x), micro_y) / accum_steps
    loss.backward()
opt.step()
I benchmarked an effective batch of 256 three ways, and this is the table that surprised me:
| strategy | time per effective batch | peak memory | throughput |
|---|---|---|---|
| direct, batch 256 | 234 ms | 10.9 GB | 1094 img/s |
| 2 × 128 | 224 ms | 5.6 GB | 1143 img/s |
| 4 × 64 | 210 ms | 2.9 GB | 1221 img/s |
Accumulation is usually sold as a compromise — same effective batch, less memory, a bit slower from the extra backward bookkeeping. On this GPU it wasn’t a compromise: 4×64 used 73% less memory and ran 12% faster than the direct batch 256. The explanation is in the earlier tables: throughput on this card peaks around batch 64 (1221 img/s) and drifts down as batches grow and memory pressure mounts, so four efficient micro-steps beat one lumbering big one. Large monolithic batches are an assumption worth benchmarking, not a law.
One honesty clause, again involving batch norm: with accumulation, BN computes statistics per micro-batch of 64, not per 256 — so this is not bit-for-bit equivalent to the direct run for BN models (norm-free and layer-norm architectures don’t care). Whether that matters for final accuracy is task-dependent and I haven’t measured it; what I measured is speed and memory, and on those axes the result is unambiguous. Remember to divide the loss by the accumulation count, or you’ve silently multiplied your learning rate.
The order I’d pull these levers
My takeaway list, in the order the evidence supports: watch peak memory against physical VRAM and keep a hard eye out for the silent cliff — on Windows, consider disabling sysmem fallback so failure stays loud. When a batch doesn’t fit, reach for accumulation first: it’s five lines, and here it cost nothing at all — it paid. Reach for checkpointing when even the micro-batch is too fat, and budget its real price, about a quarter of your throughput for 40% of your memory. And treat “bigger batch = better utilization” as a claim about someone else’s GPU until your own throughput table says so — mine says the sweet spot is batch 64, and I’d have kept scaling past it on faith.