I Moved Image Augmentation to the GPU: 13x Faster, With One Catch
Last week’s benchmark ended with CPU workers as the best available answer on Windows: 8 persistent workers turned a 17-second epoch into 4 seconds. But my pipelines post had listed a second lever I never measured — moving the transforms themselves onto the GPU. torchvision’s transforms.v2 API accepts plain tensors, works on whole batches, and runs on CUDA devices, which makes the experiment almost embarrassingly easy to set up. So: same machine (16-core CPU, RTX 4080 Super), same methodology, one new contender.
The test data is 4,096 synthetic 224×224 uint8 images living in RAM. That choice is deliberate — no JPEG decoding, no disk I/O, so the numbers isolate augmentation cost and nothing else. Real pipelines pay a decode tax that stays on the CPU either way. The augmentation stack is an ordinary ImageNet-style recipe, built once and used by both pipelines:
from torchvision.transforms import v2

tfm = v2.Compose([
    v2.RandomResizedCrop(224, antialias=True),
    v2.RandomHorizontalFlip(),
    v2.ColorJitter(brightness=0.4, contrast=0.4, saturation=0.4),
    v2.GaussianBlur(5),
    v2.ToDtype(torch.float32, scale=True),
    v2.Normalize(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]),
])
The CPU pipeline applies tfm per sample inside __getitem__, like every tutorial ever written. The GPU pipeline loads raw uint8 batches with zero workers, ships them to CUDA, and applies the same tfm to the whole batch at once:
for x in loader:          # raw uint8 batches, num_workers=0
    x = x.to("cuda", non_blocking=True)
    x = tfm(x)            # batched augmentation on the GPU
Before the results, one confession. My first benchmark run crashed with the most Windows error there is: An attempt has been made to start a new process before the current process has finished its bootstrapping phase. I had put the dataset construction at module level without an if __name__ == "__main__": guard — so each of the 8 spawned workers re-executed the whole script on import, rebuilt the ~600 MB dataset, and started benchmarking inside the worker. After writing an entire post about Windows spawn semantics, I stepped directly onto the rake. Guard your entry point; spawn re-imports your main module, and everything at the top level runs once per worker.
The results
Epoch times over 4,096 images, augmentation plus transfer to GPU, two epochs each:
| Pipeline | epoch 1 | epoch 2 |
|---|---|---|
| CPU transforms, num_workers=0 | 7.9 s | 8.1 s |
| CPU transforms, nw=8 + persistent | 9.9 s | 2.2 s |
| GPU batched transforms, nw=0 | 0.5 s | 0.16 s |
The GPU pipeline is 13.5x faster than the best CPU configuration I found last week, and 50x faster than the single-process baseline. It also has no spawn tax, no worker RAM duplication (note the 9.9-second first epoch on the worker row — that’s eight processes each receiving a pickled copy of the dataset), and no cross-process batch serialization. Per batch of 64, the entire augmentation stack costs about 1.5 ms of GPU time — small enough to hide behind most models’ forward passes, though it does compete with training for the same device.
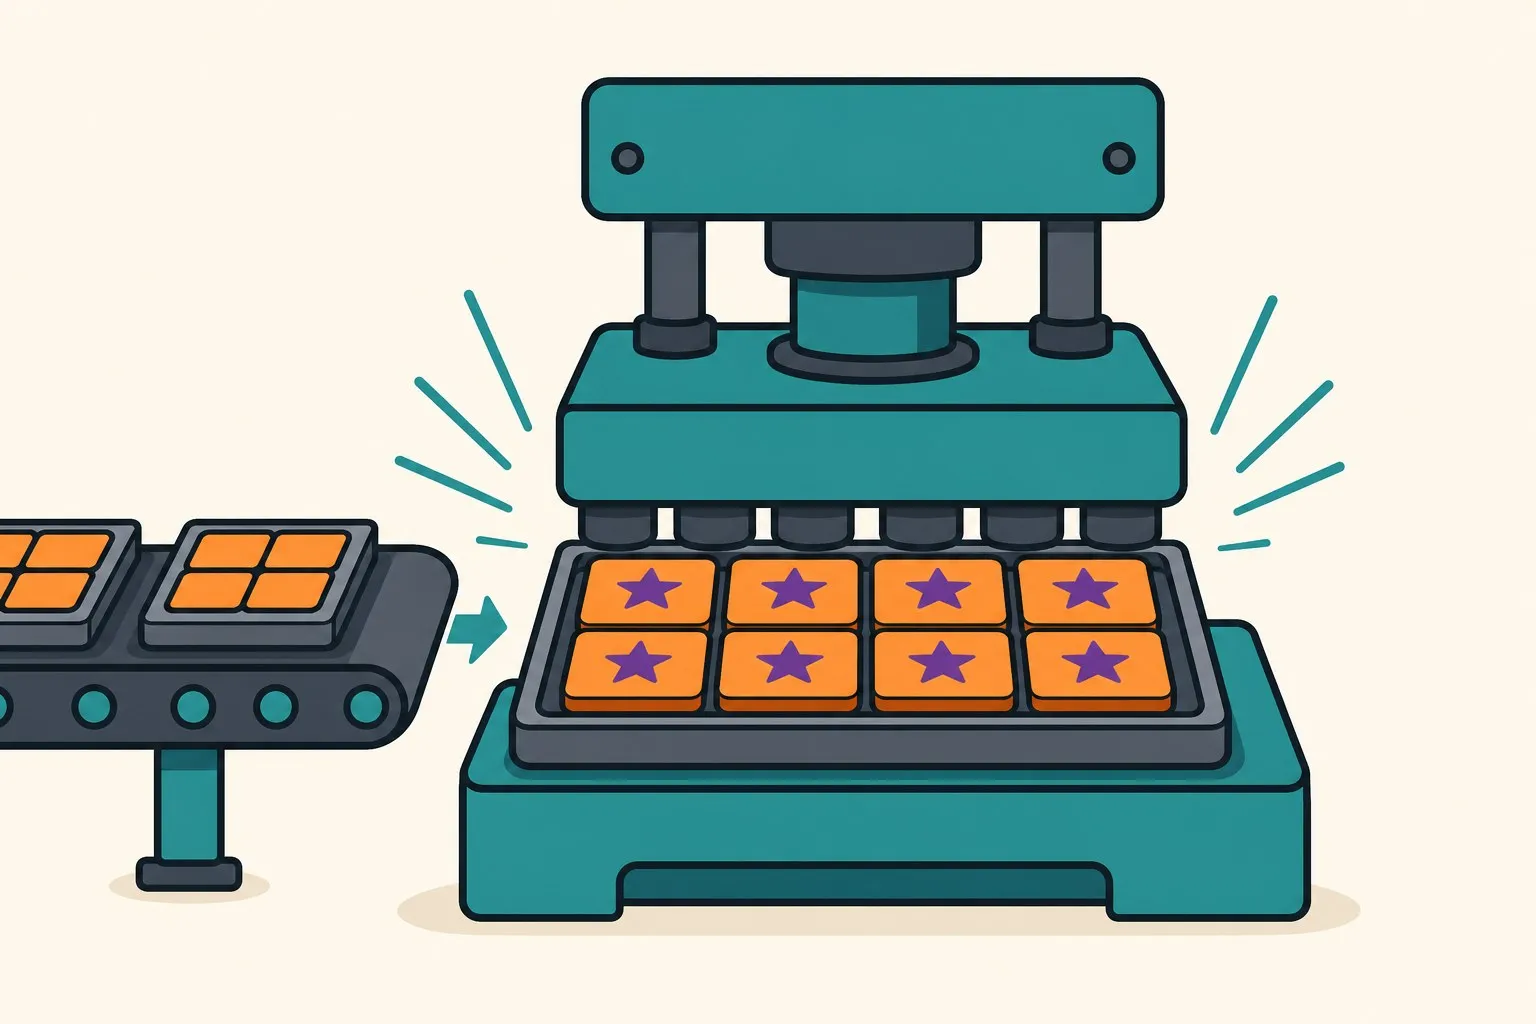
I expected the GPU to win. I did not expect a 50x margin. When one option is an order of magnitude ahead, the benchmark usually isn’t the interesting part anymore — the fine print is.
The catch: one dice roll per batch
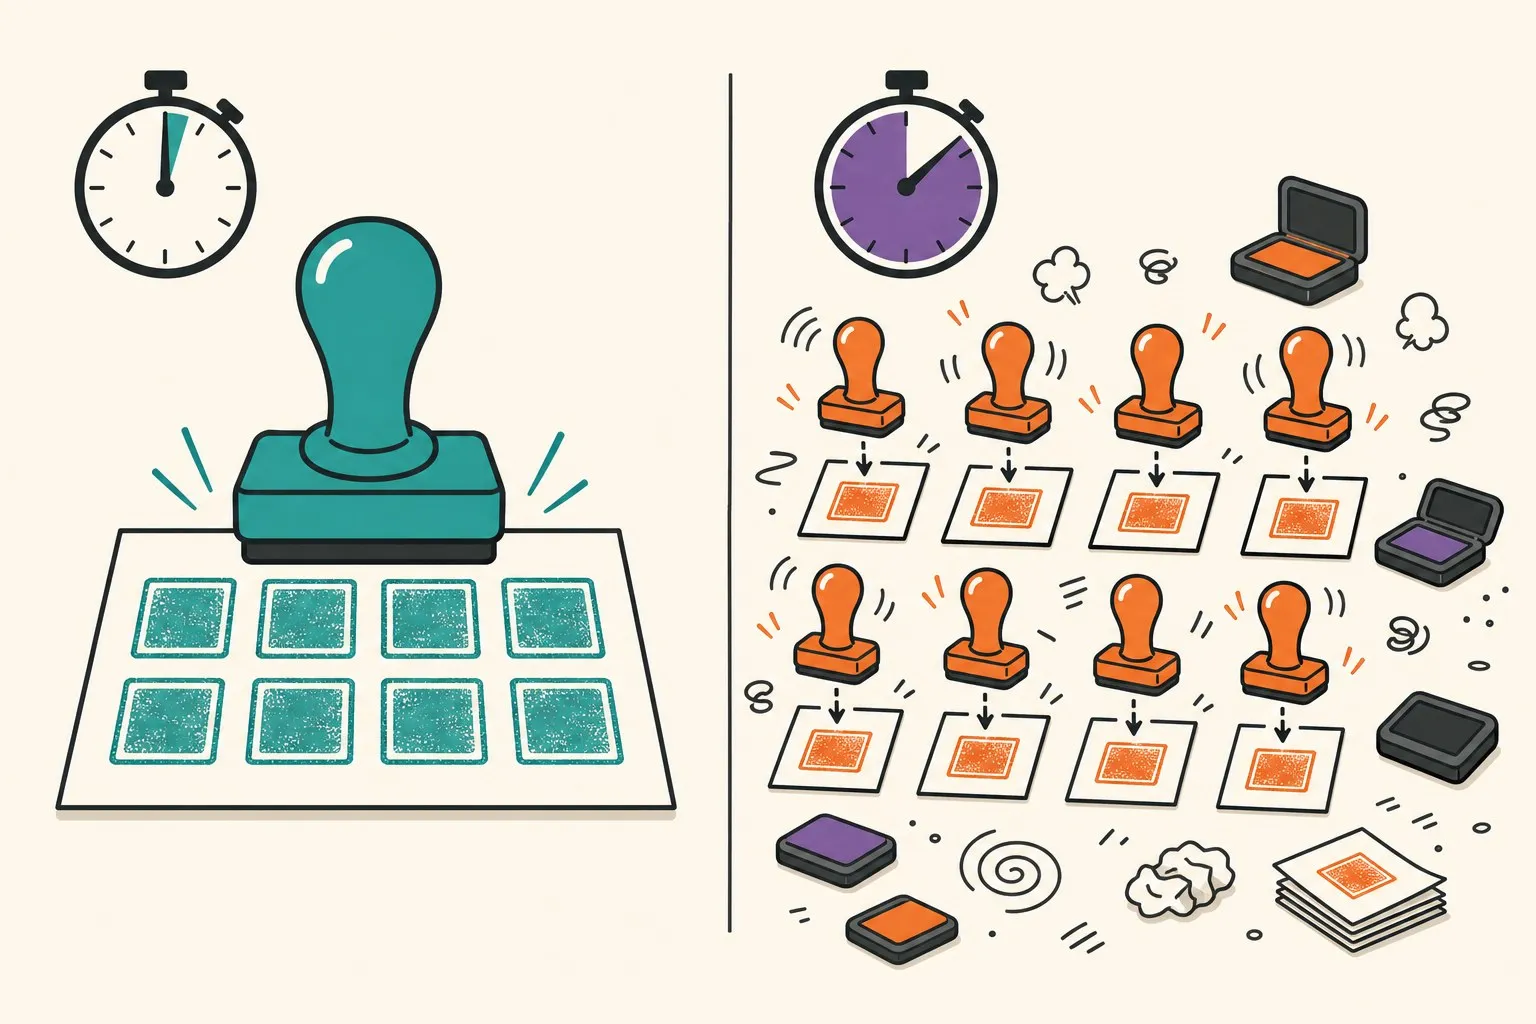
Here is the fine print, and it doesn’t appear in a timing table. A v2 random transform samples its parameters once per call. Called on a single image, that’s one crop rectangle per image. Called on a batch of 64, it’s one crop rectangle — the same one — for all 64 images. Same jitter factors, same blur sigma, same flip decision for the entire batch.
I verified it directly rather than trusting my reading of the source: eight identical images with a white stripe, through v2.RandomRotation(degrees=30) as a batch — all eight outputs bit-identical, one shared angle. The same eight images through the transform one at a time — seven out of seven rotated differently from the first:
rot = v2.RandomRotation(degrees=30)
out = rot(batch)   # (8, 3, 64, 64) -> every image rotated by the SAME angle
outs = torch.stack([rot(batch[i]) for i in range(8)])  # independent angles
So batched GPU augmentation quietly changes what “random augmentation” means: with batch size 64, you get 64x fewer distinct augmentation parameters per epoch. Nothing warns you. The images look correctly augmented individually; you’d only notice by comparing within a batch, which nobody does.
The obvious fix is 42x slower
My first instinct was the loop you see above — keep the GPU, apply per sample. Measured: 1.5 ms per batch batched, 62.5 ms per batch looping. The 42x penalty comes from launching every kernel 64 times on tiny tensors, which is exactly the workload GPUs hate. At 62.5 ms per batch, the per-sample GPU loop costs 4 seconds per epoch — slower than the CPU worker pipeline it was supposed to replace. Dead end, measurably.
What are the honest options, then? You can accept per-batch parameters — across a full epoch you still see many parameter draws, just batch-granular; whether that costs accuracy is task-dependent, and I haven’t measured it yet (it’s the obvious follow-up experiment, and I’d rather measure it than guess in print). You can split the difference: keep the cheap spatial randomness (crop, flip) per-sample on the CPU where it costs microseconds, and move only the expensive photometric ops to the GPU — you lose per-sample blur/jitter diversity but keep per-sample geometry. Or you can reach for a library built for exactly this problem: Kornia’s augmentation module samples parameters per sample while still executing batched on the GPU. I haven’t benchmarked it, so it gets a pointer here rather than a number — its whole design exists because the trade-off in this post is real.
Where this leaves my pipeline
For my own work the decision splits cleanly by workload. The windowed IMU datasets don’t touch any of this — their __getitem__ is a slice, and last week’s conclusion stands: zero workers, no drama. For image training on this Windows box, batched GPU augmentation is now my default for every experiment where augmentation diversity is not the variable under study — at 0.16 seconds an epoch, the data pipeline has simply stopped being a line item. For accuracy-critical runs, I either pay the CPU worker cost knowingly or accept batch-granular randomness knowingly. The word that matters is knowingly: the 13x speedup was advertised; the shared dice roll was not.
Three posts of measuring the same pipeline from different angles, and the pattern holds: the headline number was real every time, and the asterisk next to it was never in the documentation. Measure the speedup, then go looking for what it cost you — on your machine, not mine.